Free AI Music Generator | No Sign-Up

Describe a track and MiniMax-Music3 composes it: instrumentals or songs with sung vocals, downloaded as a stereo WAV. Free, no sign-up, no watermark.

  • No account
  • No ads
  • No watermark
Examples · tap to try

Describe the music you want, pick a target length, leave it instrumental or switch vocals on and add lyrics, then press Generate Music. Powered by MiniMax-Music3.

More Free Tools

Discover more free tools to enhance your creative projects, no account required.

Our Premium Tools

Access highly advanced AI tools with flexible pricing: subscription or one-time payment.

Muse ImageNano Banana 2Nano Banana ProGPT Image 2Grok Imagine Image 2Nano Banana 2 LiteSeedream 4Seedream 5 ProGPT Image 1.5Flux 2 ProFlux 2 MaxQwen Image 2 ProGrok Imagine ImageIdeogram V4MAI Image 2.5Nano BananaImagen 4Seedream 3Seedream 4.5Flux Kontext MaxQwen Image 2Recraft V4Recraft V4.1Krea 2Imagen 3Seedream 5 LiteFlux 1.1 ProFlux 2 KleinFlux Kontext ProZ Image TurboRecraft V3P-Image IdeogramIdeogram V3Flux SchnellWan 2.2Qwen ImageP Image UpscaleSeed VR 2FluxStable DiffusionGANQwen Edit 2511Flux Fill ProQwen EditFlux Kontext FastMiniMax H3 Max TurboMiniMax H3Grok Imagine Video 1.5Seedance 2Seedance 2.5Grok Imagine VideoSeedance 1.5 ProKling 2.5 ProRunway Gen 4.5Veo 3.1LTX 2.3 FastLTX 2.3 ProLTX 2.5 FastP-VideoSeedance 1 ProLTX 2 DistilledP-Video DraftSeedVR 2FlashVSRRTX VSR
01 · Image Generation

Generate Images with the World's Best AI Models

Generate completely new images from text prompts and reference images.

02 · Image Editing

Edit Images at Full Resolution

Edit images with simple text prompts, or mask specific areas to regenerate only what you want while keeping the rest of the image at full resolution.

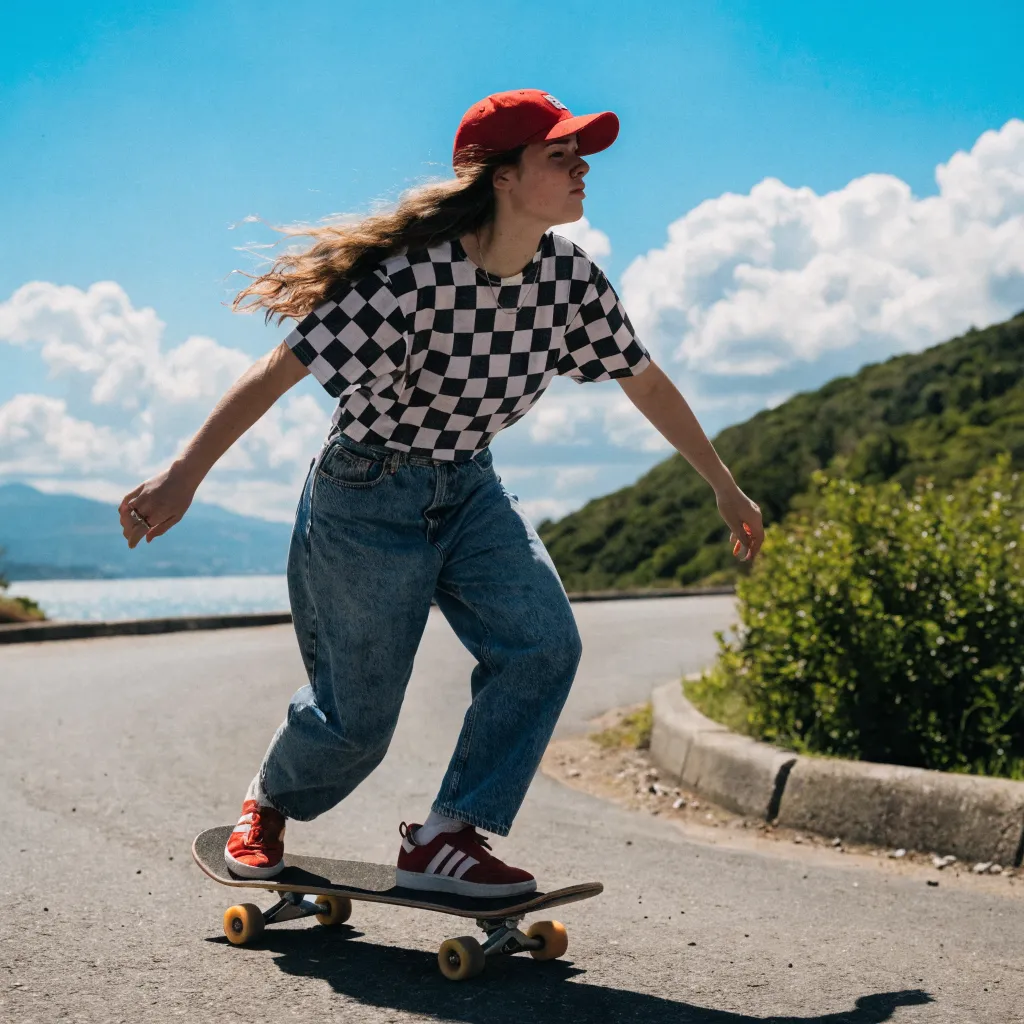
Before
Skater girl before and after editing before enhancement and upscaling
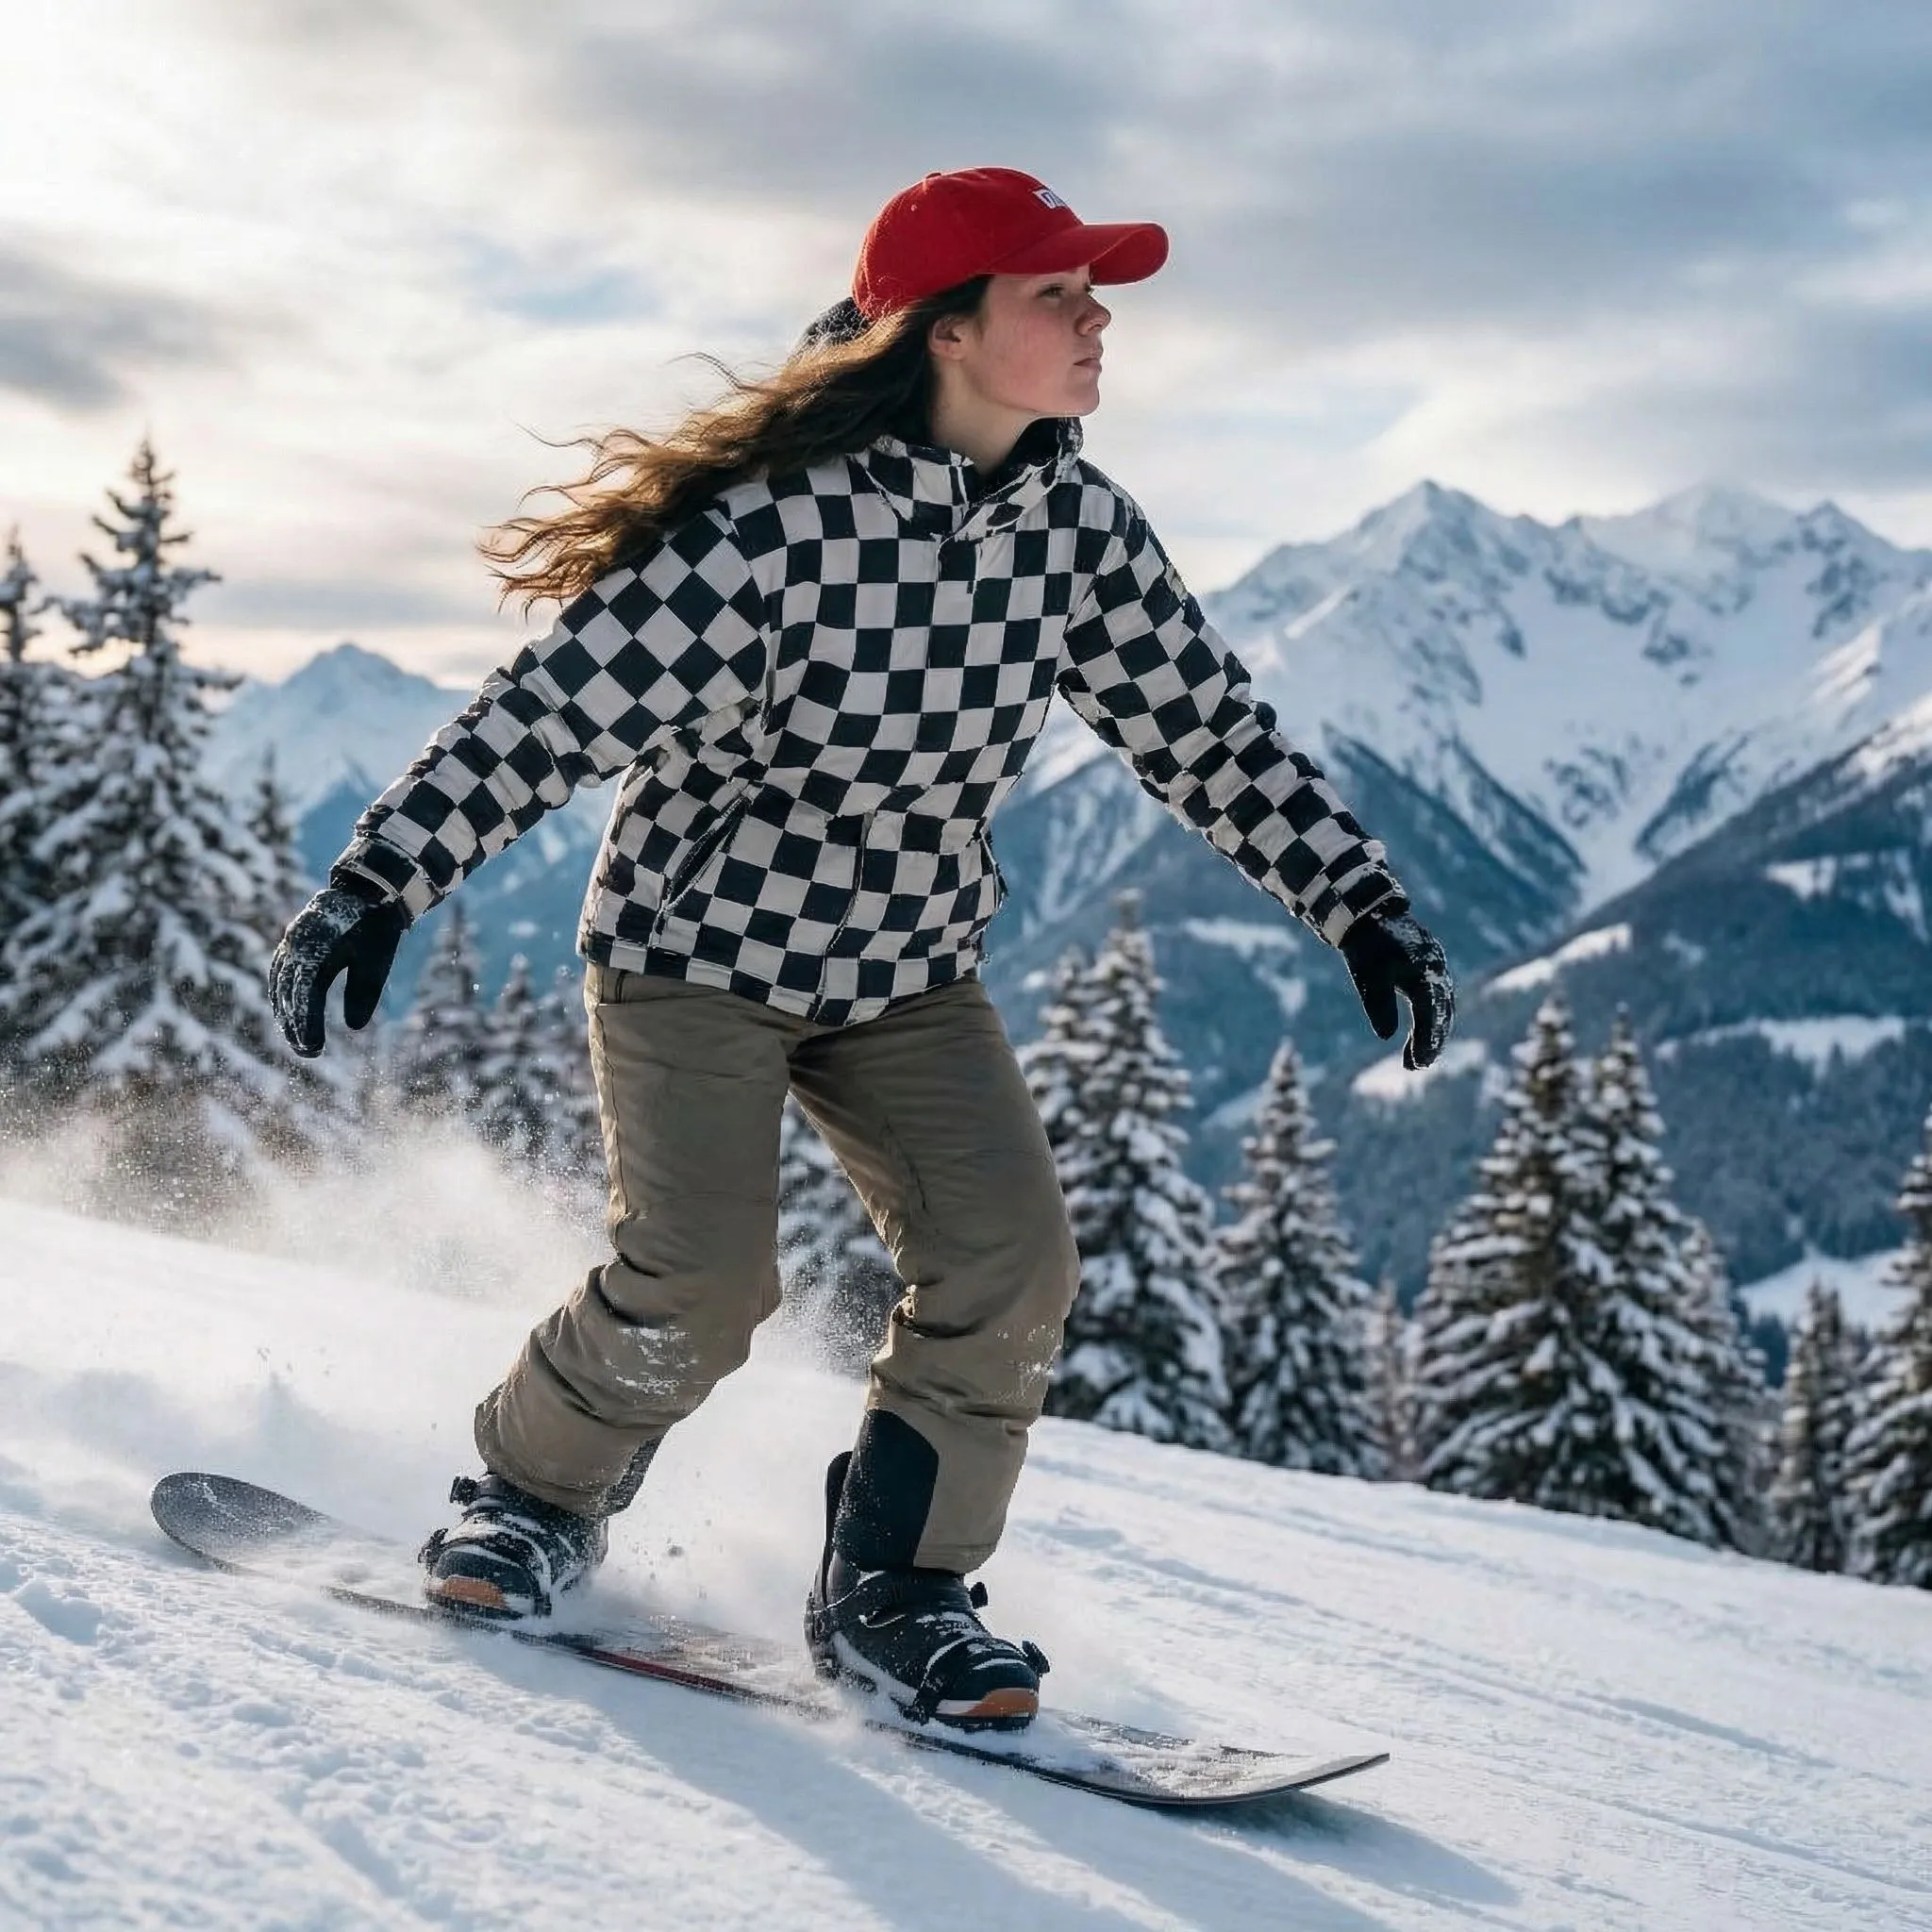
After
Skater girl before and after editing after enhancement and upscaling
03 · Image Upscaling

Upscale and Enhance Images with AI

Increase image resolution and add ultra-fine detail.

Before
Japanese supermarket enhanced, demonstrating the AI art upscaler before enhancement and upscaling
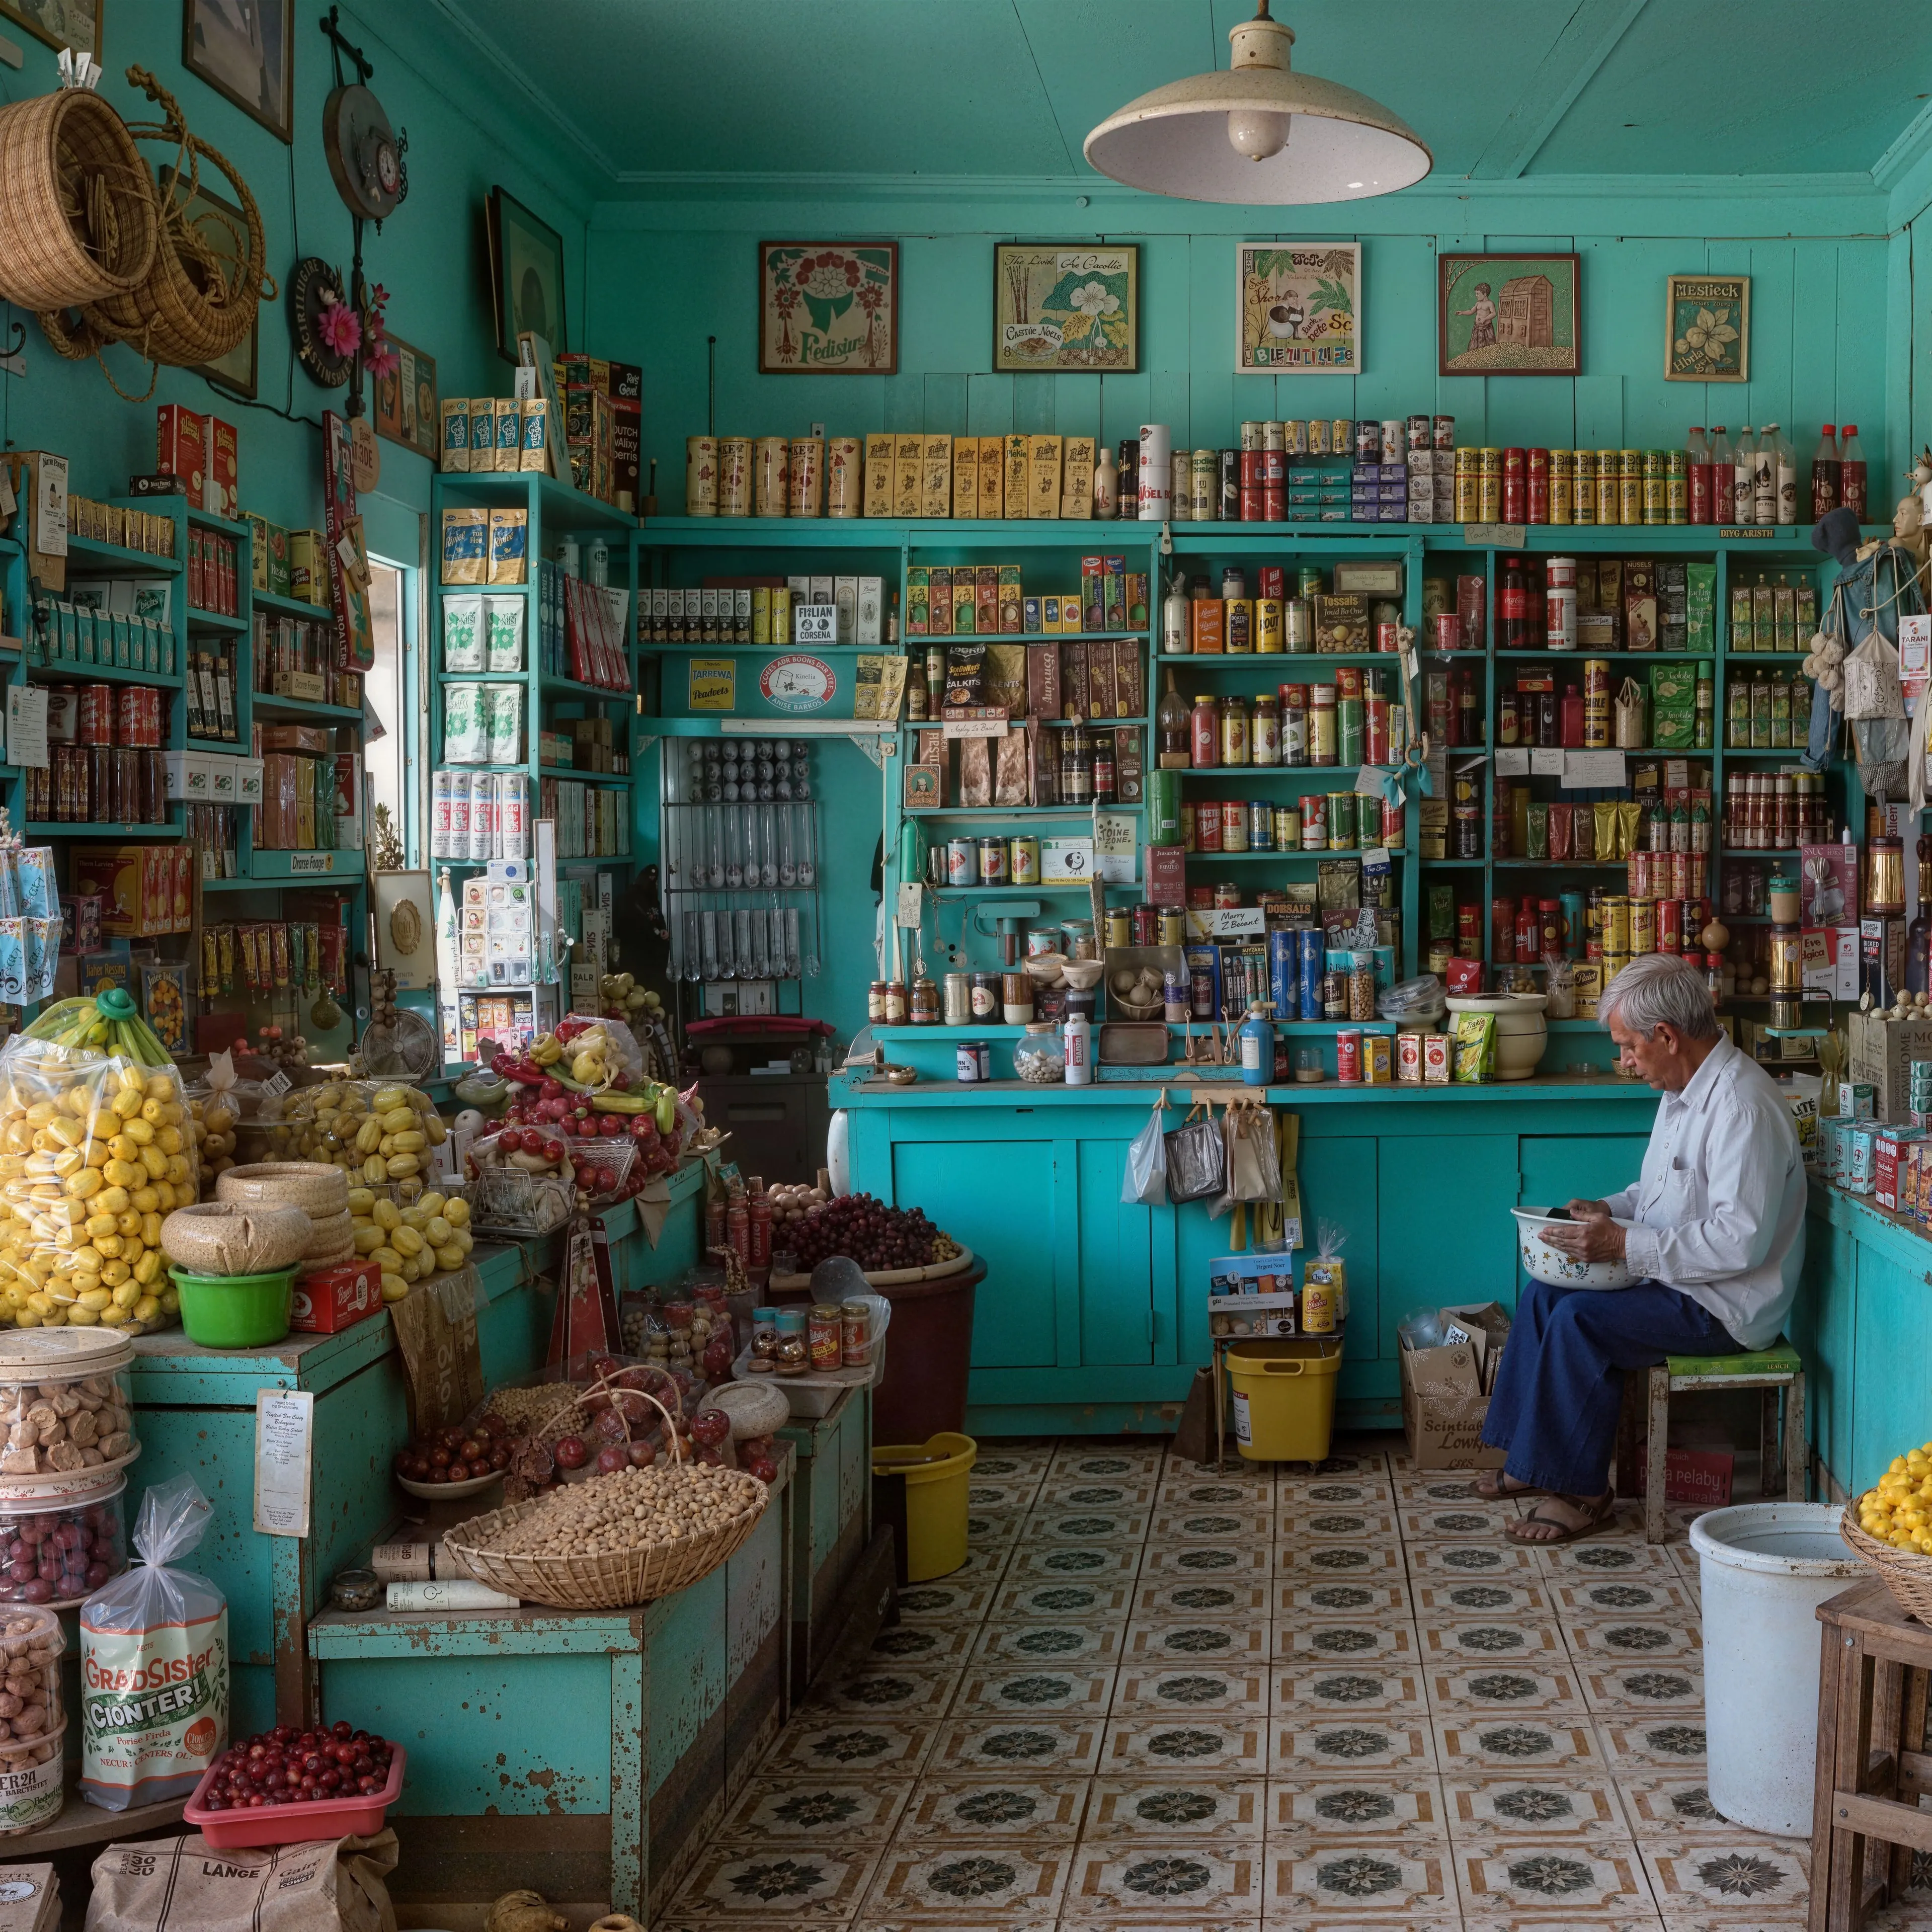
After
Japanese supermarket enhanced, demonstrating the AI art upscaler after enhancement and upscaling
04 · Video Generation

AI Video Generation Made Simple

Generate videos from text prompts, or animate existing images into smooth, natural motion.

05 · Video Upscaling

Upscale Videos to Crisp 4K

Increase video resolution up to 4K with state-of-the-art video super-resolution.

Text to music, powered by MiniMax-Music3

Type a description of a piece of music and this tool composes it: a finished mix with instruments, arrangement, and, if you want them, sung vocals. It runs MiniMax-Music3, an open music generation model, on free shared GPUs, and it hands back a 44.1 kHz stereo WAV you can download immediately. There is no sign-up, no email, no watermark, and no spoken audio tag stamped over the result.

Generating music is a different job from the image and video models elsewhere in this collection. Nothing is being stitched together from a sample library; the model writes the audio itself, which is why a description naming a genre, an instrument, and a tempo gives you far more control than a one word request. If you want moving pictures to go with the track, the free AI video generator makes short clips from the same kind of text prompt.

Instrumental beds and songs with vocals

The instrumental switch decides whether anyone sings. Left on, you get an instrumental: background music for a video, a podcast intro, a game loop, a track for a slideshow, a bed under a voiceover. That is the mode most people want, because an instrumental sits underneath narration without fighting it for attention.

Switch it off and the model performs vocals. You can hand it your own words in the lyrics box, one line per line, and it will sing them, or you can leave the box empty and let the model write words that fit the description you gave. Vocal takes are less predictable than instrumentals. Pronunciation wanders on unusual names and invented words, and the phrasing is the model's choice rather than yours, so generating two or three takes and keeping the best one is normal practice.

Most of what people make here is short and functional: a bed under a product demo, a title sting, an intro and outro pair for a podcast, a loop for a game menu, a jingle for a shop video, a piece of scoring for a wedding slideshow. Because a new take costs nothing but the wait, it is worth generating several and choosing by ear rather than trying to nail the description on the first attempt. Save the ones you like as you go; the file lives on the temporary storage of a shared server and will not be there tomorrow.

Writing a description that gets the track you want

The model reads plain English, so write as though you were briefing a musician instead of typing keywords. Four things carry most of the weight: genre, instrumentation, tempo or energy, and mood. A brief like "slow, melancholic acoustic guitar ballad with brushed drums and a warm upright bass" gets you somewhere. "Sad song" does not.

Production language works too. Terms such as lo-fi, vinyl crackle, tape saturation, reverb heavy, sparse, four on the floor, and half time all land, because the model learned from descriptions written the way music is actually talked about. Describing what an artist sounds like is more useful than naming the artist. Every run uses a fresh random seed, so the same description gives a new take each time you press the button, and pressing it again is a legitimate way to steer.

Length, quality, and limits

You can aim for about fifteen or thirty seconds. Treat that as a target rather than a promise: the model shapes a piece toward the length you request and stops where the music stops, so a thirty second request often comes back a little under thirty seconds. The player under your result reports the real length of the file that arrived, not the number you asked for, so you always know what you are working with before you drop it into a timeline.

The download is a 44.1 kHz stereo WAV, CD sample rate and uncompressed, ready for a video editor or a DAW without a conversion step. Runs happen on shared free GPUs, so every visitor gets a daily allowance and a busy period can mean a short wait in the queue; connecting a free Hugging Face account raises that allowance and improves your place in line. Nothing you type is kept: the description and any lyrics travel to the GPU for the length of the run and the generated file expires from temporary storage on its own. If the audio you need is already inside a video you have, the free video to MP3 tool pulls it out in your browser without uploading anything.

Frequently Asked Questions

Describe the music in the box above, pick a target length, leave it instrumental or switch vocals on, and press Generate Music. The track plays in the browser and downloads as a WAV. No sign-up, no email, no watermark.

MiniMax-Music3, an open music generation model, running on free shared GPUs. It generates the audio itself rather than assembling loops from a sample library.

Both. Instrumental mode is on by default. Turn it off and a lyrics box appears: paste your own words and the model sings them, or leave it empty and the model writes lyrics to match your description. Vocal takes vary more than instrumentals, so try a couple of runs.

You can aim for about 15 or 30 seconds. The model treats that as a target rather than an exact cut, so a request usually lands close to the length you chose and sometimes a little shorter. The result view reports the actual length of the file you received. Longer tracks cost more of the shared GPU allowance per run, which is why the free tool caps out at 30 seconds.

A 44.1 kHz stereo WAV, uncompressed and at CD sample rate, so it imports straight into any video editor or DAW with no conversion. Nothing is added to the audio: no watermark, no spoken tag, no signature tone.

Yes, that is what instrumental mode is for. Describe the mood and instrumentation you need, generate a few takes, and pick the one that sits best under your voiceover. Pair it with a clip from the free AI video generator if you need footage too.

Tracks are generated on shared free GPUs, and each visitor gets a daily number of runs for nothing: no sign-up, no watermark. Connecting a free Hugging Face account raises the number and gives you a better place in the queue.

Yes. Your description and any lyrics are sent to the GPU only for the length of the run, and the generated file lives in temporary storage that expires on its own. Nothing you write or generate ends up in a public gallery or a training set.

No. Your download is the clean, full-quality result with no watermark, and you never need an account or email to get it.

Yes. The tool runs open models released under the MiniMax-Music3 Community License, which claims no rights over the output you generate, so the model puts no claim on what you make, in commercial work or anywhere else. What the model does not decide is your right to the material you feed it: anything you upload stays subject to whoever holds the rights in it, and the usual limits apply either way. Do not use the tools to create illegal content, to impersonate real people, or to infringe someone else's rights.

No. Uploads and prompts are screened by an automated safety filter before anything runs, and sexually explicit content and anything involving minors are blocked and cannot be unlocked on any plan. Our Terms of Service list the full set of prohibited content.